The Evolution of the SOC: From Manual Overload to Autonomous Decision-Making
The modern Security Operations Center is drowning in noise. Analysts face thousands of alerts daily, many of them false positives, while genuine threats hide in the flood. This alert fatigue breeds a dangerous normalization of deviance—when everything is critical, nothing is. The human cost is equally severe: burnout drives experienced analysts out of the industry, creating a talent vacuum that further strains remaining teams. Meanwhile, mean time to respond (MTTR) stretches into hours or days as investigators manually copy-paste indicators between tools, consult outdated wikis, and wait for approvals. Attackers exploit precisely this delay, moving laterally through networks while defenders read documentation.
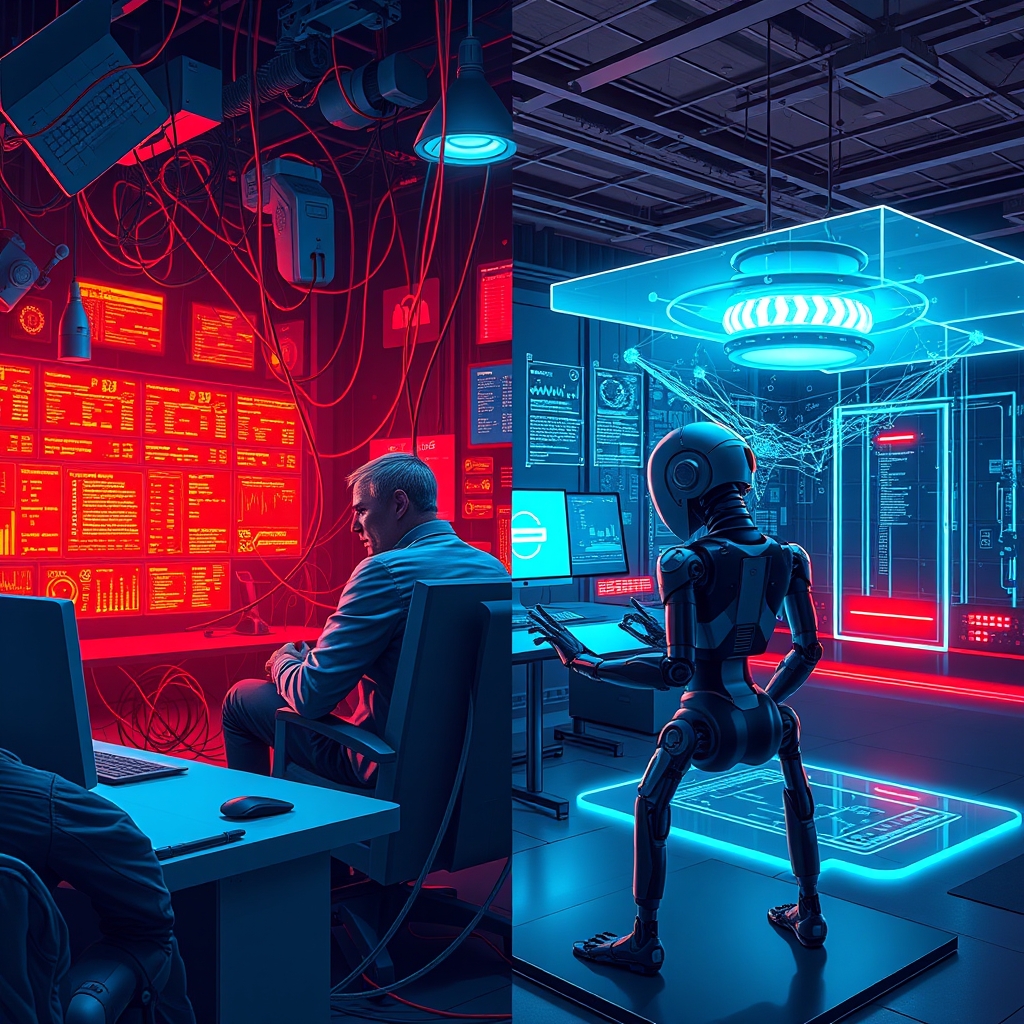
Traditional SOAR platforms promised relief but delivered only partial liberation. Their playbooks excel at repetitive, linear tasks: enriching an IP with a threat feed, quarantining a known-bad file hash, opening a ticket. But playbooks are deterministic scripts—they follow if-then logic paths written in advance. They cannot reason about ambiguous evidence, adapt to novel attack sequences, or weigh competing hypotheses about an incident. The moment an alert falls outside a predefined scenario, the SOAR stops and the human must resume the cognitive load.
The Agentic SOC represents a paradigm shift beyond both manual investigation and static automation. It is built on three defining principles:
Autonomy means agents can pursue goals independently—not merely executing predefined steps, but selecting which tools to use and which actions to take based on the situation.
Reasoning is the capacity to hold a mental model of an incident, generate hypotheses, test them against evidence, and revise conclusions as new data arrives—much like an experienced analyst.
Orchestration is the intentional coordination of multiple specialized agents, each handling different aspects of an investigation, collaborating and escalating to humans only when necessary.
Where SOAR asks, "What should I do next according to this flowchart?" an Agentic SOC asks, "What is actually happening here, and what is the best response?" That difference—from procedural execution to contextual understanding—is what makes autonomy possible.
Core Building Blocks: Understanding AI Agents and Their Architecture
Before you can design a self-driving SOC, you must understand the engine under the hood. The distinction between a chatbot and a true AI agent is not academic—it is the difference between a helpful assistant and a digital analyst capable of closing an incident. This foundation matters because the architectural choices you make here determine everything that follows: how agents perceive threats, how they remember past incidents, how they plan investigations, and how they translate decisions into actions.
A chatbot responds. It waits for human input and generates text based on its training data. An AI agent, by contrast, acts. It is goal-driven: given an objective like "investigate this suspicious login," it independently reasons about the steps required, selects and invokes tools, and iterates until the goal is met or it escalates. Where a chatbot might suggest a query to run, an agent runs the query, evaluates the results, runs a follow-up query, and then opens a ticket with a recommended containment action.
Internally, agents follow a cognitive loop with five components:
- Perception ingests structured and unstructured data—alerts, logs, endpoint telemetry, threat feeds—and converts it into a working representation.
- Memory spans both short-term context (the current investigation) and long-term stores (vector databases of past incidents, playbooks, and organizational knowledge).
- Planning decomposes goals into ordered, conditional steps. A planner might decide: first query the SIEM for related events, then pull the host timeline from the EDR, then check threat intel for the IP reputation.
- Action executes those steps via tool calls. Tools are wrappers around APIs: querying Splunk, isolating a host in CrowdStrike, searching VirusTotal, creating a Jira ticket.
- Reflection evaluates whether actions moved the agent closer to the goal. Did the query return useful context? Is the evidence sufficient to close or escalate? Reflection enables the agent to revise its plan rather than blindly executing a script.
Single agents are powerful, but complex security workflows demand collaboration. Multi-agent frameworks distribute responsibilities across specialized agents—one for triage, one for malware analysis, one for containment. Two orchestration patterns dominate:
- Supervisor-worker, where a central orchestrator agent decomposes tasks and delegates to specialist agents, then synthesizes their outputs. This mirrors an SOC lead assigning work to analysts.
- Peer-to-peer (or decentralized), where agents negotiate directly, sharing findings and requesting actions from one another. This suits dynamic, unpredicted workflows but requires careful governance to avoid loops.
The final building block is integration. An agent that cannot reach your security stack is a brain without hands. Seamless, API-driven connections to the SIEM (for correlation and historical context), EDR (for endpoint state and response actions), threat intelligence platforms (for reputation and adversary context), and ticketing systems (for tracking and human handoff) are non-negotiable. Without integration, the agent lacks both the context to reason accurately and the ability to execute meaningful actions. Integration is what transforms an AI experiment into an operational SOC component—and it is the bridge to the workflow design that comes next.
Designing the Self-Driving Security Workflow
With the architectural foundations in place, we can now examine how these components combine into an operational system. The core of an Agentic SOC is a continuous, cyclical workflow that mirrors a seasoned analyst's process, but at machine speed and scale. This loop is composed of four integrated phases.
Autonomous Triage: Cutting Through the Noise
The initial flood of alerts is where most SOCs drown. Agentic triage tackles this head-on. The moment an alert surfaces—from an EDR, firewall, or cloud platform—a dedicated agent claims it. The agent's first task is correlation, linking this isolated event to others. It queries the SIEM for related login failures from the same IP, looks for matching endpoint processes, or connects the alert to a recent user behavioral anomaly. Instead of treating each event as distinct, the agent builds a unified incident candidate.
Next, the agent enriches this candidate with context. It performs reverse DNS lookups, queries threat intelligence platforms for IP/domain/hash reputation, checks the asset's criticality from the CMDB, and pulls the affected user's role and past security incidents. With this full picture, a reasoning engine scores severity, not just on raw alert priority, but on a composite of asset criticality, threat intel reliability, prevalence of the indicator, and the strength of the correlation. Low-scoring, benign events are auto-closed with a full audit trail, instantly eliminating the majority of noise that burdens human analysts.
Investigation and Hypothesis Generation
Once an incident is elevated as suspicious, the workflow transitions from triage to a dedicated investigation agent. This agent's goal is to determine the story of the attack—not merely to confirm that something is wrong, but to understand what happened, how it happened, and what the attacker is after. It begins by generating a set of hypotheses: Is this a credential-stuffing attack? A malware beacon? An insider threat?
For each hypothesis, the agent defines a set of evidence-gathering actions. It might query the EDR for the process tree leading to a suspicious event, pull network flow logs to see where the host communicated, or retrieve a suspicious file and detonate it in a sandbox. The agent then reasons over the collected evidence to support or refute each hypothesis. It might ask, "If this is C2 beaconing, do the connection intervals match a known pattern?" or "Does the suspicious process have a valid digital signature?" This is not a scripted playbook; it's an iterative, goal-directed exploration where the agent decides its next query based on the answer to the last one, mimicking a human analyst's deductive process. The output is a structured incident narrative with a proposed root cause and recommended next steps.
Remediation and Containment
With a clear understanding of the threat, an orchestration agent proposes a response. For low-confidence or low-impact actions, like blocking a known-bad domain on a web proxy, it may be authorized to act autonomously. For higher-risk actions, the workflow emphasizes human-in-the-loop (HITL) controls. The agent prepares a "response ticket" containing its full reasoning, evidence chain, and a precise recommended action: isolate endpoint FIN-PC-221, disable user account jdoe, or block SHA256 hash d41d....
A human analyst reviews this pre-packaged decision, approves or modifies it with a single click, and the agent then executes the change via the appropriate API (EDR, identity provider, firewall). This model ensures that critical decisions retain human oversight, while removing the toil of manually navigating consoles and typing CLI commands.

Continuous Learning
The final, crucial phase closes the loop and connects the workflow back to the trust-building mechanisms we will explore in the next section. Every action and outcome is logged. Did the enrichment data prove useful? Was a hypothesis proven correct? If an analyst overrides an agent's recommendation—for example, by reclassifying an incident as a false positive or choosing a different containment method—this signal is captured.
These feedback loops are fed back into the system. Prompts are refined, the weights in the scoring model are adjusted, and the knowledge base is updated so that the next time a similar pattern emerges, the agent is more accurate. This continuous learning from expert corrections and real-world outcomes is what elevates an Agentic SOC from mere automation to true, evolving expertise.
The Human-Agent Teaming Model in the SOC
The workflow we have just described raises an inevitable question: where do humans fit? The Agentic SOC is not a story of replacement but of partnership. The core question is not whether agents will act, but how much latitude they receive. This spectrum is best understood through three operating modes.
In assistive mode, agents act as tireless advisors. They observe alerts, gather context, and surface recommendations—for example, "This login pattern resembles a known credential-stuffing attack" or "Suggests quarantining endpoint 10.4.2.17." The human analyst retains full decision authority. This mode is ideal for onboarding teams to agentic workflows, building familiarity without operational risk.
Supervised mode shifts agents into execution with a check valve. Here, an agent will automatically enrich the alert, query the SIEM, and draft a containment playbook. But before executing a sensitive action—isolating a host, disabling a user account, or blocking an IP at the firewall—it pauses for explicit human approval. The agent presents its proposed action, supporting evidence, and confidence score; the analyst clicks approve or reject. This balance accelerates response while maintaining human accountability. Most production SOCs should operate primarily in this mode for high-severity incidents.
Autonomous mode grants agents full control over well-bounded workflows. For low-risk, high-volume tasks—phishing triage, stale account cleanup, or low-confidence alert suppression—agents act end-to-end without human intervention. The condition for autonomy is a strict policy envelope: agents may only perform actions pre-approved by security leadership, on scoped resources, with mandatory logging.
Building Trust Through Transparency
Autonomy cannot be granted without trust, and trust is earned through three mechanisms. Explainability means every agent decision is accompanied by a natural-language rationale: which evidence was weighed, which hypotheses were considered and discarded, and why a given action was selected. An agent that says "I isolated this host because three corroborating signals exceeded thresholds" invites verification; one that acts silently invites suspicion.
Audit trails must capture more than the final action. They should record the agent's perception (what data it saw), its planning (which playbook it selected), its reasoning (the intermediate steps), and every external tool call. This immutable log serves both operational forensics and regulatory compliance—a point we will return to when discussing implementation challenges.
Confidence scoring gives the analyst a quick way to triage agent decisions. A remediation proposed with 0.98 confidence can be approved in a glance; one at 0.62 demands deeper review. Over time, these scores should be calibrated against real-world outcomes—a feedback loop that sharpens both agent and analyst judgment.
The Analyst Role, Redefined
This model fundamentally alters the analyst's job. The daily grind of manually triaging hundreds of alerts disappears. Instead, the analyst becomes an agent overseer: monitoring multiple agent workflows via dashboards, reviewing flagged exceptions, and stepping in where confidence is low or novelty is high. The "exception handler" role is not passive; it concentrates human expertise where it matters most.
Simultaneously, freed from the queue, analysts shift to proactive work: threat hunting, hypothesis generation, adversary emulation, and refining agent playbooks. This requires different skills than the traditional SOC role. Analysts need enough understanding of agent architecture to debug flawed reasoning, enough data literacy to evaluate explainability outputs, and enough systems thinking to design new autonomous workflows. Security professionals become, in effect, managers of synthetic analysts: setting objectives, defining guardrails, and auditing performance.
The shift is not just operational but psychological. Analysts who once defined their value by incident count must now define it by outcome quality and systemic improvement. Organizations that invest in this transition—through training, tooling, and cultural change—will unlock the full potential of the Agentic SOC. And that investment must be built on a technology foundation that can actually deliver on these promises.
Enabling Technologies and the Integration Stack
Powering an Agentic SOC demands a carefully assembled technology stack where each layer reinforces the others—the same way the four workflow phases depend on each other. At the foundation sits the large language model itself. Selection criteria extend beyond benchmark scores to include context window size (critical for correlating lengthy alert histories), tool-calling reliability, latency under concurrent agent load, and security-specific fine-tuning aptitude. While general-purpose models understand basic security concepts, fine-tuning on incident reports, threat write-ups, and your organization's historical playbooks narrows the gap between plausible-sounding text and actionable security reasoning. This specialization helps agents distinguish between a routine port scan and a targeted reconnaissance pattern.
Retrieval-augmented generation grounds agent outputs in authoritative, current sources. Instead of relying solely on parametric memory, agents query vector databases containing threat intelligence feeds, MITRE ATT&CK mappings, vendor advisories, and internal runbooks. When a novel alert arrives, the agent retrieves semantically similar past incidents and current threat actor TTPs before formulating a hypothesis. This reduces hallucination and ensures responses reflect the latest intelligence rather than stale training data.
Tool-use protocols transform agents from conversationalists into operators. Standardized interfaces such as OpenAPI specifications, MCP (Model Context Protocol), and function-calling schemas allow agents to query SIEMs, execute EDR containment actions, or open tickets. Secure credential management is paramount. Agents should never hold static API keys; instead, use short-lived tokens issued by an identity-aware proxy that scopes permissions to specific actions and resources. Just-in-time elevation with human approval for destructive operations adds another control layer.
Event streaming platforms like Apache Kafka or AWS Kinesis feed agents normalized security telemetry in real time. Batch processing introduces unacceptable delays; streaming ensures an agent triaging a phishing alert receives related proxy logs and email gateway metadata within seconds, enabling rapid containment.
Guardrails constitute the final and most critical layer. Policy engines intercept every agent action, evaluating it against allowlists, blast-radius limits, and separation-of-duties rules. For example, an agent may quarantine a workstation but cannot disable MFA. Sandboxed execution environments, immutable audit logs of all agent reasoning chains, and kill switches that immediately suspend autonomous operations provide defense-in-depth. These mechanisms ensure the Agentic SOC remains a controlled, auditable system rather than an unsupervised digital actor.
Measuring the Effectiveness of an Agentic SOC
Even with the right technology stack in place, deploying an Agentic SOC is a significant investment, and justifying that investment requires more than anecdotal evidence of "fewer alerts." Organizations need a rigorous, quantitative framework to assess whether autonomous agents are truly delivering on their promise. Without clear metrics, an Agentic SOC risks becoming an expensive experiment rather than a transformative capability. The most effective measurement approach uses a balanced scorecard that spans three critical categories: time-based operational metrics, quality metrics, and executive-level operating metrics.
Time-Based Metrics: The Core of Incident Velocity
The foundational metrics for any SOC—manual or autonomous—are the time-based measures that track how quickly an incident moves through its lifecycle. These metrics are where the speed advantage of AI agents should be most immediately visible.
Mean Time to Detect (MTTD) measures the interval between an attacker's initial action and the organization's awareness of that activity. Traditional MTTD is often inflated by signal noise, under-tuned detection rules, and analyst backlogs. An Agentic SOC improves MTTD in two ways: first, by continuously correlating low-level signals across disparate sources to identify patterns that individual rules miss; second, by eliminating the queue time between alert generation and human review. Agents are always "on," never fatigued, and can process telemetry streams in real time. An effective Agentic SOC should demonstrate a measurable reduction in MTTD, particularly for attacks that rely on subtle behavioral anomalies rather than known signatures.
Mean Time to Investigate (MTTI) covers the period from initial detection to a confirmed understanding of the incident's scope, root cause, and severity. This is often the most time-consuming phase in a traditional SOC, requiring analysts to manually query multiple systems, correlate logs, and build a mental model of the attack chain. AI agents excel here. They can autonomously execute investigation playbooks, query EDR telemetry, pull threat intelligence, examine network flows, and assemble a comprehensive incident timeline in seconds. The key question is not just whether MTTI drops, but whether the investigation is complete. An agent that reduces MTTI by 90% but misses critical context is not a success. Effective measurement should therefore pair MTTI with investigation completeness scores—assessing whether the agent identified all affected assets, correctly attributed the attack, and surfaced the most relevant evidence.
Mean Time to Respond (MTTR) measures how long it takes to take a meaningful action after an incident is understood. In a supervised Agentic SOC, this includes the time an agent waits for human approval on containment actions. Autonomy should reduce MTTR by minimizing unnecessary handoffs. For well-understood, low-risk incidents—such as confirming a known phishing URL or isolating a compromised test server—agents can act immediately under predefined policy. For high-risk actions, the agent can prepare everything in advance so that when a human approves, execution is instant. A well-designed Agentic SOC will show MTTR dropping dramatically for routine incidents while remaining appropriately deliberate for complex threats.
Mean Time to Contain (MTTC) tracks the interval between initial detection and full containment of the threat—when the attacker's access is severed and the incident can no longer spread. MTTC is the ultimate measure of incident velocity. Agents improve MTTC by reducing every preceding phase and by executing containment actions across multiple systems simultaneously. A human analyst might isolate endpoints one by one; an agent can issue parallel API calls to isolate fifty endpoints, revoke credentials, and block network segments in under a minute. This parallelism is a capability advantage that should show up clearly in MTTC measurements.
Quality Metrics: Ensuring Speed Doesn't Compromise Accuracy
A common failure mode in automation initiatives is that speed improvements come at the cost of quality—faster but wrong. Quality metrics are therefore essential to validate that the Agentic SOC is not just fast, but good.
False positive reduction rate measures how effectively the agentic pipeline filters out non-threatening alerts before they reach a human analyst. A traditional SOC might forward 70% of alerts to humans, many of which turn out to be benign. An Agentic SOC should show a substantial increase in the percentage of alerts autonomously resolved as false positives, with a corresponding drop in alerts requiring human intervention. The metric should be tracked as a ratio: alerts correctly classified as benign versus alerts incorrectly dismissed as benign. The latter is the dangerous failure mode, and it should be near zero.
Accuracy of root cause analysis evaluates whether the agent's conclusions about an incident are correct when subsequently reviewed by human experts or validated by later evidence. This can be measured through post-incident reviews, where senior analysts score the agent's incident summaries, attack chain reconstructions, and identified root causes. Over time, organizations can track a rolling accuracy score—the percentage of agent-performed investigations where the human reviewer agreed with the agent's conclusion without material correction. This metric also feeds directly into trust: consistently high root cause accuracy is what earns agents more autonomy.
Analyst satisfaction scores are often overlooked but critically important. If the Agentic SOC is working correctly, analysts should spend less time on tedious triage and more time on intellectually engaging threat hunting and complex incident response. Satisfaction can be measured through regular surveys that assess analysts' confidence in agent decisions, their perception of workload quality, and their willingness to grant agents additional autonomy. A high-performing Agentic SOC should show improving satisfaction scores over time. Declining scores are an early warning sign that the system is creating new frustrations—perhaps by requiring excessive human oversight, generating confusing outputs, or creating a "rubber stamp" dynamic where analysts feel they are just clicking approvals without adding value.
Operating Metrics: What Leadership Cares About
While time and quality metrics matter to security practitioners, executives and board members need operating metrics that translate agentic performance into business outcomes.
Overall automation rate is the percentage of all security alerts and incidents that are handled end-to-end by the autonomous system without any human intervention. This is the headline number that demonstrates the ROI of the Agentic SOC. A mature deployment might automate 80-90% of routine alerts while escalating only genuinely novel or high-severity incidents to humans. Tracking this metric over time also reveals whether the system is learning—an effective Agentic SOC should show a gradual increase in automation rate as agents accumulate institutional knowledge and analysts expand the scope of trusted autonomous actions.
Cost per incident handled is a financial metric that combines staffing costs, tooling costs, and infrastructure costs divided by the number of incidents processed. Traditional SOCs show a relatively flat cost curve because adding capacity requires adding headcount. An Agentic SOC should demonstrate a declining cost per incident as automation scales—the marginal cost of an agent processing one more alert is near zero. This metric is particularly compelling when communicating with leadership, as it translates technical capability into the language of operational efficiency.
Attack surface coverage measures the breadth of the environment that the autonomous system actively monitors and protects, including endpoints, cloud workloads, identity systems, network segments, and SaaS applications. Traditional SOCs often focus disproportionately on high-visibility systems while leaving gaps in less-glamorous areas. An Agentic SOC's ability to monitor comprehensively and without fatigue should result in measurably broader coverage. This can be quantified as the percentage of registered assets that are actively monitored by agents, with alerts being correlated and investigated by the autonomous pipeline.
The Necessity of a Balanced Scorecard
No single metric tells the full story. An SOC that achieves lightning-fast MTTR but poor root cause accuracy is dangerous. A system with a high automation rate but declining analyst satisfaction is unsustainable. A deployment that reduces cost per incident but leaves critical attack surface unmonitored is a false economy. The balanced scorecard approach ensures that speed, quality, and efficiency are all tracked simultaneously, and that trade-offs between them are made visible. Organizations should review the full scorecard regularly—monthly for operational metrics, quarterly for quality and satisfaction metrics—and use the insights to calibrate autonomy levels, refine agent policies, and guide training data improvements. The goal is not to maximize any single metric, but to demonstrate that the Agentic SOC is making the organization simultaneously faster, more accurate, and more efficient.
Implementation Challenges and Risk Management
However compelling the metrics case may be, building an Agentic SOC is not a frictionless march toward autonomy. It demands honest confrontation with technical, organizational, and regulatory hurdles that can derail even well-funded initiatives. Recognizing these challenges early—and designing mitigations into the system from the start—is the difference between a resilient deployment and a costly failure.
Technical Risks: Novel Attacks, Prompt Injection, and Hallucination
The most acute technical risks stem from the inherent limits of machine learning models. A zero-day attack, by definition, shares no signature with historical training data. An agent trained on yesterday's threats may misclassify a novel exploit as benign, or worse, fail to escalate it. Adversarial prompt injection poses a second danger: attackers can craft malicious content—inside phishing emails, log files, or even threat intelligence feeds—designed to manipulate an agent into ignoring policy, exfiltrating data, or executing unintended tool calls. Finally, model hallucination can fabricate evidence, invent false correlations between alerts, or generate root cause analyses that sound authoritative but are entirely wrong. In security, a confident false conclusion is more dangerous than no conclusion, because it triggers automated containment actions based on fiction.
These technical risks are not merely theoretical—they are the direct inverse of the trust mechanisms described in the human-agent teaming model. Where explainability, audit trails, and confidence scoring create the conditions for human oversight, prompt injection and hallucination attack those very foundations. This is why guardrails, sandboxed execution, and kill switches must be treated as first-class architectural requirements rather than afterthoughts.
Organizational Resistance and Cultural Shift
Technical failures are compounded by human resistance. Security analysts may fear that agents will replace them, or they may simply distrust decisions made by a model they cannot interrogate. If an agent wrongly isolates a production server, trust evaporates quickly. Change management must be explicit: position agents as force multipliers that eliminate toil, not as replacements for human judgment. Provide transparent audit trails and allow analysts to override agent actions at any time. Invite skeptics into the design process rather than imposing automation from above. The redefined analyst role we outlined earlier—agent overseer, threat hunter, workflow designer—will only be embraced if the transition is managed with respect for existing expertise and honest communication about the future.
Regulatory, Compliance, and Forensic Considerations
Autonomy introduces legal complexity. When an agent executes a containment action—such as deleting a file or blocking an IP—regulators may ask: who authorized this? Maintaining a tamper-evident chain of custody is non-negotiable. Every agent action must be logged with full context: the input, the model's reasoning, the tool called, the parameters, and the human approval status. For forensic investigations, you need immutable records that can be replayed in court or during post-incident review. Comply with data residency and privacy regulations when agents process sensitive telemetry. The audit trail requirements here extend beyond the operational logging discussed in the trust section; they must satisfy legal standards of evidence and regulatory scrutiny.
Scaling Safely: Start Low, Prove, Then Expand
The path to autonomy is incremental. Begin with low-risk, high-volume workflows: phishing triage, enrichment of known indicators, or evidence summarization. In these areas, a mistake is annoying but not catastrophic. Measure false positive rates, analyst approval rates, and override frequency. Only after reliability is proven over months should you graduate to semi-autonomous containment, and then to fully autonomous response for well-understood threat classes. Autonomy is earned, not granted. This staged approach mirrors the phased adoption roadmap we will now explore in detail.
The Road Ahead: Realizing the Fully Autonomous SOC
The journey toward a self-driving SOC is not a distant science fiction fantasy—it is a pragmatic roadmap unfolding in stages. Organizations that begin now will be positioned to ride the wave of autonomy rather than being swamped by it. The challenges are real, but they are navigable with the right preparation.
Near-term wins are already within reach for teams willing to experiment. Fully autonomous phishing triage, where agents parse suspicious emails, extract indicators, analyze attachments in sandboxes, and either quarantine or escalate without human touch, can eliminate the most repetitive volume of SOC work. Automated malware analysis follows naturally: agents can orchestrate detonation, collect behavioral telemetry, and generate verdicts in minutes rather than hours. Automated endpoint isolation—triggered by high-confidence signals—removes the "golden hour" delay that often separates a contained incident from a breach. These are not theoretical; they are buildable today with existing tools.
Long-term possibilities push toward a genuinely anticipatory security posture. Imagine predictive defense: agents that model attacker behavior, simulate likely intrusion paths against your actual network topology, and preemptively harden weak points before a campaign begins. Self-healing systems take this further—detecting configuration drift, unauthorized changes, or vulnerability exposure and automatically restoring known-good states without human intervention. Fully automated threat hunting—where agents continuously generate hypotheses from threat intelligence, query endpoint and network telemetry, and pursue leads with the persistence of a human hunter but at machine speed—becomes the default operational tempo.
How to Prepare Today
The foundation for this future is built on three pillars—the same pillars that have anchored every stage of the journey we have described, from architecture through workflow design to teaming models and metrics.
Skills. Your SOC team must evolve from ticket resolvers to agent overseers. Invest in prompt engineering, automation architecture, and agent behavior analysis. Analysts should learn to evaluate agent decisions, not simply perform them. Data science literacy—understanding confidence scores, drift, and model evaluation—becomes a core SOC competency. This is not an optional add-on; it is the human counterpart to the technical stack.
Data foundations. Agents are only as capable as the context they can access. Build a unified, searchable security data lake that integrates SIEM, EDR, cloud logs, and threat intel. Invest in strong entity resolution and knowledge graphs so agents can reason over relationships, not just raw logs. Clean, labeled historical data is your most valuable asset for training and fine-tuning. Without this foundation, even the most sophisticated agent architecture will underperform.
Phased adoption roadmap. Start with low-risk, high-volume workflows. Phase one: deploy assistive agents that summarize alerts and recommend actions, with humans approving everything. Phase two: move to supervised autonomy for containment actions—endpoint isolation, account suspension—with strict guardrails and automatic rollback. Phase three: enable autonomous triage and investigation for clearly scoped alert types. Phase four: expand to threat hunting and predictive analytics, with continuous feedback loops refining agent behavior. At each stage, measure containment accuracy, mean time to respond, and—critically—analyst satisfaction. The goal is not to replace your team but to amplify their judgment, turning your SOC from a reactive help desk into a proactive defense organism that never sleeps.
Share article
Daniel Mercer
Senior Cybersecurity Analyst
Daniel Mercer is a Senior Cybersecurity Analyst with extensive experience in evaluating and improving security training programs. He focuses on identifying gaps in employee knowledge and developing targeted solutions to enhance organizational resilience.
View author profile ↗